I’ve worked with — and consumed — some absolutely dreadful APIs.
Zero documentation.
Inconsistent naming.
Responses that change shape constantly.
Endpoints that behave differently for no obvious reason.
The kind of APIs where you’re not integrating… you’re reverse engineering. Sometimes it feels like behaviour changes based on temperature, lunar cycle, or wind direction.
I once knew a software architect who’d put together endpoints like this.
POST /getProductDetailsDude was POSTing to get. I assumed there must be some complex payload involved. Maybe filtering. Maybe transformation rules. Maybe some deep, stateful process.
Nope. You’d send:
{
  "productId": 42
}
Sometimes the response would be:
{
  "id": 42,
  "name": "Desk",
  "price": 199.99
}
But depending on some product variable, that response could be:
{
  "data": {
    "productId": 42,
    "productName": "Desk",
    "unitPrice": "199.99"
  }
}
FML. Like… really?
This isn’t rocket science (Unless you’re literally building flight systems for NASA. In which case, carry on).
An API is a contract. If you break contracts casually, people stop trusting you.
Verbs Matter
HTTP already solved this.
GETretrievesPOSTcreatesPUTreplacesPATCHupdatesDELETEdeletes
If I see:
POST /deleteUserI immediately assume chaos lives here.
Correct:
DELETE /users/42It’s self-documenting. No guessing. Simple.
Idempotency
If I call this five times:
PUT /users/42
{
  “email”: “[email protected]”
}
The end result should be exactly the same as calling it once.
The user’s email becomes [email protected].
That’s it.
Not:
1st call → updates successfully
2nd call → creates a duplicate record
3rd call → increments a hidden “update counter”
4th call → triggers a webhook again
5th call → 500 error because “email already set”
But why does this matter? Well, in the real world:
Mobile apps retry requests.
Load balancers retry requests.
Network timeouts cause clients to retry.
Humans double-click buttons.
An idempotent update endpoint should answer this question:
“If I replay this request, does the system end up in the same state?”
Versioning
If your API evolves (and it will) don’t mutate behaviour silently.
Don’t wake up one Tuesday and decide price is now unitPrice.
Do this instead:
/api/v1/products/42
/api/v2/products/42
Breaking changes go into new versions. Old clients continue working. Contracts are respected.
Validation & Error Codes
Don’t do this:
200 OK
{
  "error": "Something went wrong"
}
That’s not OK.
Use status codes properly:
200– success201– created204– no content400– bad request401– unauthorised404– not found422– validation error500– our fault (and we should log it, alert it, and fix it)
And structure errors consistently:
{
  "error": {
    "code": "VALIDATION_ERROR",
    "message": "Email is required"
  }
}
Consumers shouldn’t have to pattern-match sadness.
Pagination
If your endpoint returns 12,000 records because “the frontend can handle it” - no, no, no, no, no.
Do this:
GET /users?page=2&per_page=25And return metadata.
{
  "data": [...],
  "meta": {
    "current_page": 2,
    "per_page": 25,
    "total": 430,
    "last_page": 18
  }
}
Simples.
Filtering
Let clients ask for what they need:
/orders?status=paid
/orders?created_from=2026-01-01&created_to=2026-01-31
But whitelist allowed filters. Remember, your API is not:
/orders?where=1=1;DROP TABLE usersYou’re the captain now (not the consumer).
Includes
Only return the data that’s required. You don’t want to put unnecessary strain on the server if the consumer doesn’t require every piece of information currently available to them.
Instead of:
Get orders
Then all the customer data attached to the order returned as well.
Allow for:
/orders?include=customerReturn nested relationships intentionally.
Consistent Responses
Pick a format.
Stick to it. i.e:
{
  "data": {...},
  "meta": {...}
}
Don’t sometimes return raw objects and sometimes wrap them.
Consistency reduces cognitive load.
Authentication
Authentication isn’t just about proving someone is logged in.
It’s about:
Identifying who they are
Controlling what they can do
Each request should carry its own proof of identity:
Authorization: Bearer eyJhbGciOiJIUzI1NiIsInR5cCI6IkpXVCJ9...There’s a few approaches:
Token based access
The most straightforward approach:
Generate a long, random token
Store a hashed version in the database
Associate it with a user or system
Send it in the Authorization header
Best practices:
Show the token once on creation
Hash it in storage (like passwords)
Allow revocation
Log last-used timestamp
Allow multiple tokens per user
JWTs
JSON Web Tokens are popular because they’re self-contained. They carry claims inside them:
{
  "sub": 42,
  "role": "admin",
  "exp": 1710000000
}
Pros:
Stateless
Fast validation
Good for distributed systems
Cons:
Harder to revoke
Easy to misuse
Often over-engineered for simple APIs
If you use JWTs:
Keep expiry short
Avoid putting sensitive data inside
Use refresh tokens properly
Don’t treat them like magic
JWT is a tool. Not a silver bullet.
OAuth
Third-party integrations
“Login with X” flows
Delegated access
If you’re building a public platform where external apps connect on behalf of users, OAuth makes sense.
If you’re building an internal CRM, it probably doesn’t.
Before wrapping this section up, a couple of things that deserve more attention than they usually get:
Logging and observability.
Authentication without logging is just blind trust.
If you don’t know:
which token called which endpoint
how often
from where
and when
…then you don’t really have control.
Expire your tokens.
Forever tokens are a liability.
They get copied.
They get committed to repos.
They get left in old scripts.
They get forgotten.
And one day, they get abused. Expire them!
Rate Limiting
Someone is definitely going to write:
while(true) {
  callYourApi();
}
Limit requests per minute. Throttle anonymous traffic. Protect your infrastructure from enthusiasm.
Documentation
If your API requires a Slack message to understand it, it isn’t finished.
Minimum:
Endpoint
Method
Parameters
Example request
Example response
Error cases
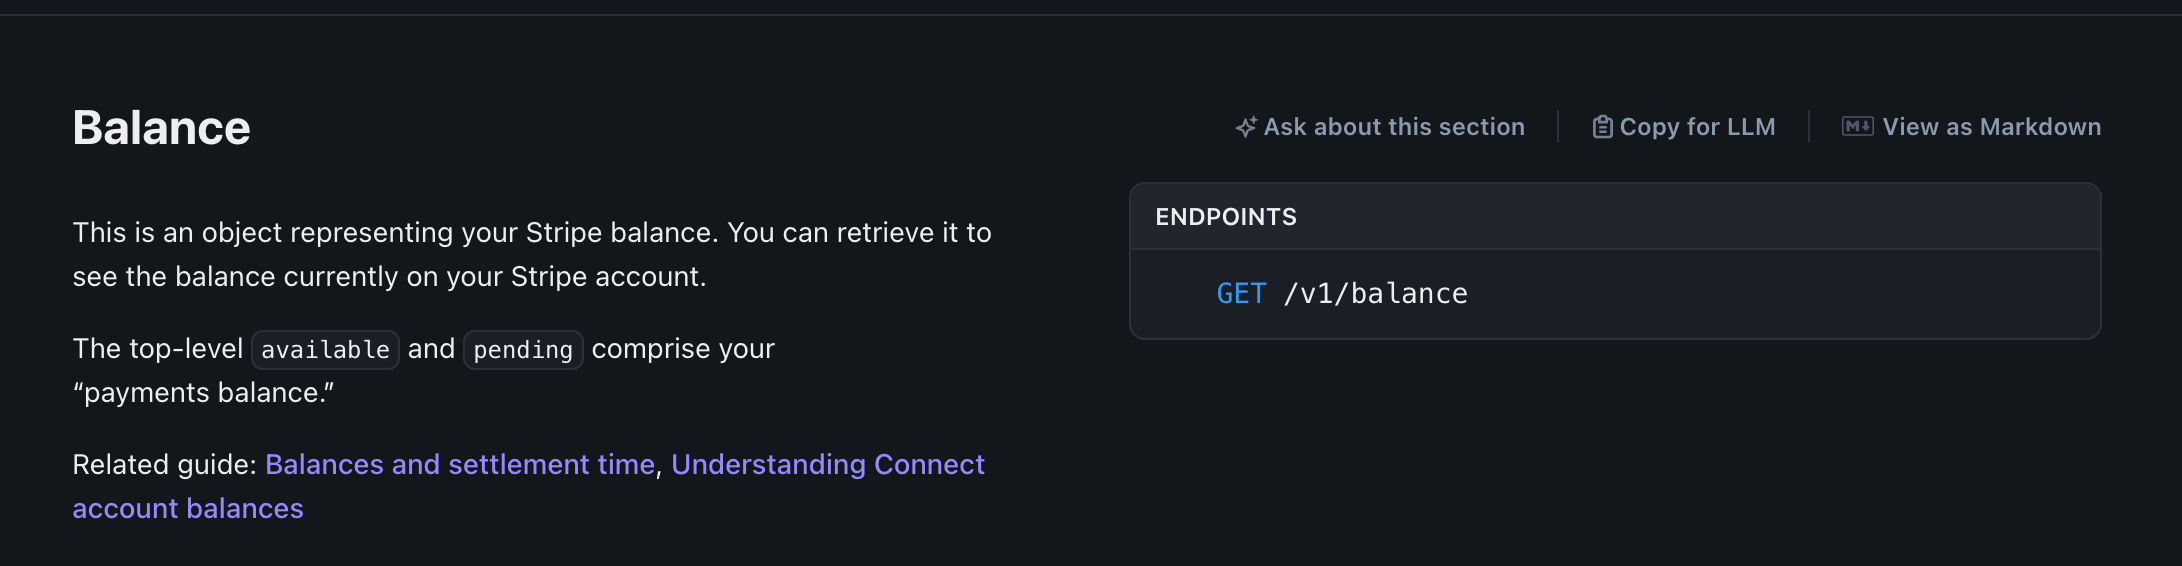
If someone has to read your backend source code to integrate… that’s unfinished work.
Conclusion
Yep so…. a good API:
Is boring.
Is predictable.
Is versioned.
Is consistent.
Is documented.
Doesn’t surprise people.
You know what bad APIs feel like. I gave you an example in the introduction.
A good example?
You can’t go far wrong with Stripe.
Check out https://docs.stripe.com/api
Also, I stole this off the Internet.
